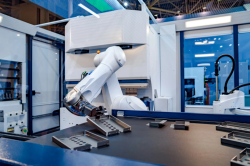
When we enter a room, we can immediately tell where each object is and notice the obstacles and changes in the surrounding space. For a robot, this is a complicated process: it needs to not only recognize an object, but also determine its location, movement, and connection to its surroundings in order to navigate the changing environment and act in it. Solutions to these problems are one of the key aspects of developing embodied intelligence.
Embodied intelligence is an approach in which AI not only works with digital data, but also interacts with the physical world via robots and other devices. Such a system can perceive its environment, analyze it, make decisions, and take actions while accounting for any changes in the surroundings. Unlike conventional AI systems that can work exclusively with digital information, embodied AI can acquire data directly from the physical world and learn by interacting with it.
As the name suggests, this field is the main focus of ITMO’s Laboratory “Embodied AI and Robotics”. Headed by Prof. Sergey Kolyubin, the deputy dean of the School of Computer Technologies and Control, the lab unites specialists in algorithms, control and decision-making systems, computer vision, machine learning, and generative design. The scientists work with various robotic systems, from manipulators and walking robots to quadcopters and underwater devices.
In September, the three most recent solutions by the lab and its partners were presented at the European Conference on Computer Vision (ECCV 2026). They describe the components of a single spatial intelligence system and solve different, but linked, parts of the same task of enabling robots to “sense.” FastR-4DGS, the first model, is responsible for the dynamics: it helps robots represent the scene in 3D and in time, not just as a still image. The second model, QUORUM, makes the representation semantically clear and coherent from various vantage points, and the third model, Obj3R, creates object-based spatial memory and makes it possible to account for changes in an already existing map.

Laboratory “Embodied AI and Robotics.” Credit: Dmitry Grigroyev / ITMO NEWS

Laboratory “Embodied AI and Robotics.” Credit: Dmitry Grigroyev / ITMO NEWS

Laboratory “Embodied AI and Robotics.” Credit: Dmitry Grigroyev / ITMO NEWS
Three levels of spatial intelligence
FastR-4DGS teaches robots to recognize objects not only in space, but also in time. The algorithm accounts for the way objects move and thus how the scene will look in the following moments. At the core of the solution is object recognition based on Gaussians instead of points.
When a robot follows a moving object with a camera, the system needs to constantly track how it changes its location. One of the ways to do that is to represent the object as a set of tens of thousands of points. FastR-4DGS offers a more compact representation with Gaussians – 3D elements that describe an object’s geometry, color, and other properties.
Experiments show that 9-12 Gaussians is enough to represent a single object – instead of around 40,000 points. This cuts down on the amount of data the system needs to process to track movement. Based on the movement and rotation of Gaussians, the algorithm determines how an object’s location changes in time and space.
“This solution is fit for dynamic scene reconstruction, including in AR systems, where it’s crucial to quickly and realistically represent the space with moving objects. Moreover, the technology makes it possible to synthesize data to train and test algorithms, such as control strategies for robot manipulators and autonomous vehicles. As the model accounts not only for geometry, but also for changes in time, such data can better simulate real-world situations like the movement of people, transport, and objects, as well as any other changes in the environment,” says Segrey Kolyubin, the head of the lab.

Sergey Kolyubin. Credit: Dmitry Grigoryev / ITMO NEWS
QUORUM is the model that helps a robot understand what’s around it, even if the same object looks different from different angles. In conventional systems, robots identify objects after the recording is complete or in advance based on the categories provided by developers.
QUORUM teaches the system to work with an open dictionary online, meaning it can work with queries that haven’t been included by the developers. The system incorporates observations of the same object from different angles and forms a semantic map of the dynamic scene. It connects an object’s visual properties (shape, color, structure) with its spatial representation, thus making it possible to store a complex understanding of the object, regardless of lighting, location, or angle.
The model combines several observations into a dense field of visual and language features. This allows the system to preserve the connection between the geometry of the scene and the meaning of what it contains. When an object comes into the robot’s field of view, the machine “remembers” the features it has already analyzed and recognizes it. Thanks to QUORUM, the robot will be able to find an object not only by its name, but also by its description.
The Obj3R model can remember dynamic scenes. A conventional 3D map may look like a collection of geometric points – the kind you can see in a robot vacuum app. Such a map is useful for avoiding obstacles, but it is not always convenient for meaningful action. Obj3R takes the robot’s spatial memory to the object level. Instead of an unnamed obstacle, the system learns to recognize that there is a “table” or a “chair” in front of it – objects that can move.
Thanks to this, the robot does not need to build a new map of the room every time; it updates only the part of the scene that has changed. Combined with language queries and navigation, the object map becomes the basis for instructions such as: “find the box that used to be by the door,” “drive to the table where the book previously laid,” or “pick up the object to the left of the laptop that was brought in yesterday.”
“Taken together, these three models are upgrading the spatial intelligence of autonomous semantic agents. Semantic representations allow us to communicate with machines using natural language. Another practical use case is the creation of realistic synthetic data. This makes it possible to train models and conduct primary validation of models faster and more cost-efficiently before testing them on real robots, where experiments require equipment, time, and additional security measures,” shares Sergey Kolyubin.
The lab also collaborates with various industrial partners. A part of frontier research in embodied AI is implemented within the joint research laboratory with Sberbank’s Robotics Center – the lab has contributed to the development of indoor navigation systems for wheeled and legged mobile robots. Some of the lab’s developments were tested on Green, the company’s anthropomorphic robot. In 2026, the lab’s solutions in spatial intelligence are used to develop robotization technologies in foodtech.