Researchers use neural networks and software for multiple tasks; they often turn their calculations into code so that their colleagues can use them, too. For that reason, code is just as much a a result of research as the paper itself. However, unlike with publications, finding a piece of code and its author can be a hurdle since repositories may be published privately, links get distorted, and names differ. Because of that, when looking for a particular tool or a collaborator, researchers have to manually look through publications, contact various departments and organizations, or use neural networks. Yet the latter do not always have access to the necessary websites and cannot combine data from various sources to provide the full picture.
To solve this problem, researchers from ITMO’s Institute for Artificial Intelligence designed PAUK – the first knowledge graph builder in Russia that connects organizations, employees, publications, and code. The service is named PAUK (“паук” means “spider” in Russian – Ed.) for its likeness to a spider’s web – the system follows an evidence-based approach and allows users to access data that appears beyond the reach of conventional networks, for instance, code repositories.
“The biggest difference is that unlike commonautomated parsing systems, PAUK doesn’t just guess connections; it looks for proofs at each stage. For one, the system doesn’t rely on matching names alone to assume different articles mention the same person. Instead, it verifies ORCID (Open Researcher and Contributor ID) records or corporate emails to prevent any confusion since names in articles can be written differently (for example, Ivanov Ivan or Ivanov I.). It can also happen that a researcher cites code by a different person in their paper; hence, the tool also checks if the author indeed wrote the code or refers to someone else’s tool. Should evidence be insufficient, the system puts the decision on hold or sends it for manual review to avoid mistakes that may appear because of shortened publication lists: authors may disappear from their department’s publication and developments statistics or another researcher’s tool may be cited as their own,” explains Andrey Getmanov, the team’s leader and a junior researcher at ITMO's Research Center “Strong AI in Industry.”
Andrey Getmanov. Credit: Mila Manshina
PAUK will be useful for:
-
scientists – to find research collaborators, analyze connections between different departments, and use open-source code;
-
AI agents – to find code, models, or datasets based on a method description from a paper and avoid duplicating existing technologies;
-
research managers – to see the full picture: who authors both code and papers, and where to find “hidden” experts who do not usually appear in publication reports.
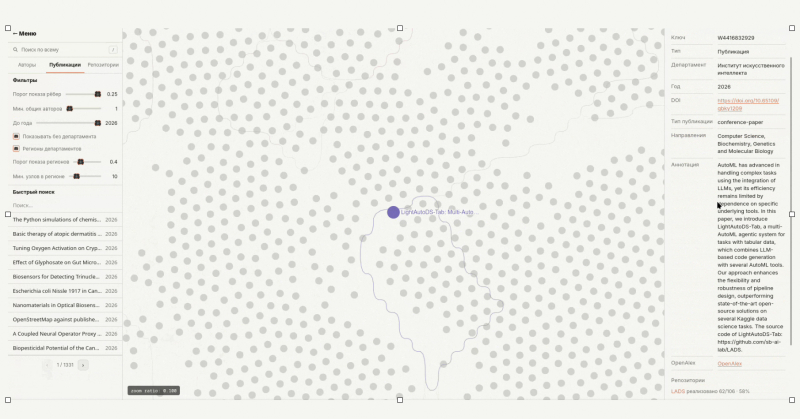
A card with ITMO publications. Image courtesy of the developers
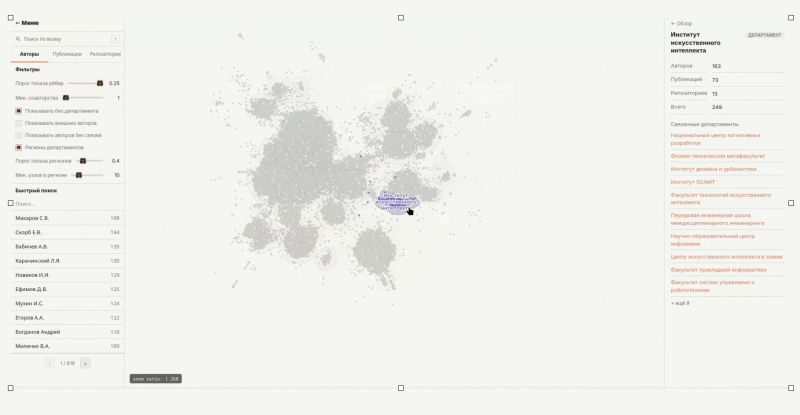
A department on the map. Image courtesy of the developers
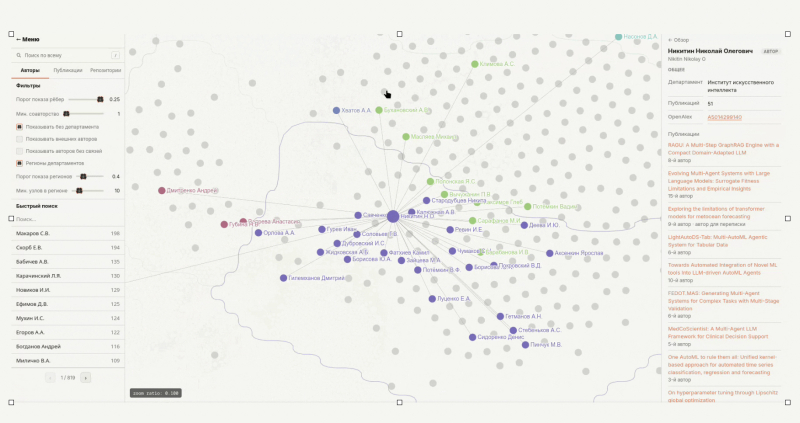
A card of an ITMO employee and their connections with other researchers. Image courtesy of the developers
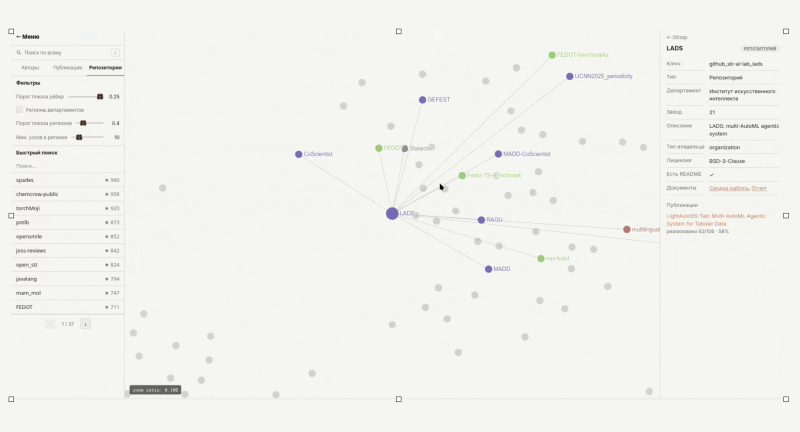
A card of an ITMO repository and its connections with other repositories. Image courtesy of the developers
PAUK performs several operations to identify an article and related materials by the name of a publication. First, the system accesses OpenAlex (an open catalog of scientific publications) and selects articles related to the query. Then, it analyzes these publications for links from GitHub and other websites and keeps only those works that contain code or a repository. Next, the service cleans and processes data: for example, it extracts links from PDF files where they might be cut off or split by spaces. Additionally, PAUK verifies authors using open data. As a result, users receive a complete picture: the article, its authors, their affiliations, and the code.
“PAUK makes finding people and tools for collaboration much easier. Imagine a chemistry team is on the lookout for experts in multiagent systems. Before, they’d need to contact other faculties to learn who exactly does that, study publication lists, and search their contacts – and this process takes a lot of time. But now, chemists can just use PAUK and get all the details with names, papers, repositories, and links,” adds Andrey Getmanov.
PAUK currently runs on-premises. The team plans to open up the service and expand its resource network by, for instance, introducing materials from unarchived workshops and open-source conferences. The developers also want to add the option for users to ask questions in everyday language, rather than by exact titles or names; the graph will also include information about participation in conferences and funding sources. In the future, the team will adapt their approach for other universities to facilitate partner search and collaboration.
The project is supported by ITMO’s 2030 Development Strategy. The team consists of 12 researchers and students of ITMO’s Institute for Artificial Intelligence, including first-year Bachelor’s students from the AI Science & Technology Lab. The service was presented at the 22nd Conference of Open Source Developers that took place on October 2-4 in Pereslavl-Zalessky.