Aptamers are short DNA and RNA molecules that can selectively bind with other molecules, proteins, and cells. Thanks to this property, they are used and studied as a basis for diagnostic tests, medicines, and biosensors. Typically, researchers have to go through multiple aptamer variants to find the one that fits a particular target. Computational models can help lower the number of experiments needed to find this variant by selecting those that have the highest probability of being effective. However, if a model can’t handle new variants well, this selection won’t be reliable.
This was the issue ITMO scientists addressed with AptaBench, a standard test for AI models that predict the interaction of aptamers and molecules. It includes experimentally-obtained data and unified verification rules that enable the comparison of different models. AptaBench’s database includes 6,289 experimentally verified interaction pairs that involve 1,610 DNA and RNA aptamers and 942 ligands. The corresponding paper was accepted for the NeuroIPS conference in the track Evaluations & Datasets.
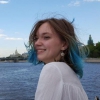
“Many interaction prediction models are assessed in relatively simple conditions when the training and test data contain similar sequences and molecules. In practice, we are often interested in brand new models or aptamers – for instance, a sequence that was generated by a different model. We wanted to see how well the results of standard testing hold up under these conditions. It turned out that the differences can be quite significant. That’s why it’s important to assess not only the model’s accuracy but also the limits of its applications,” says Maria Eremeeva, the paper’s first author and an engineer at ITMO’s Advanced Engineering School.
Maria Eremeeva. Credit: Polina Fedorova / ITMO
For AptaBench, the researchers selected only the cases where interaction between aptamers and molecules was experimentally verified. This included the pairs where experiments demonstrated that the aptamer-molecule bind is small or non-existent. That is important because in previous studies such negative examples were often artificially made with no experimental verification. A comparison demonstrated that real data is more effective for training the model: in one of the experiments, the PR-AUC metric that describes the quality of classification grew from 0.75 when using artificial negative examples to 0.95 when using experimental data.
The researchers have also suggested three ways to test the model. In the first one, the data is randomly split into training and test groups – this is the usual approach to evaluating a model’s quality. In the second, the model is tested on new molecules, different in their chemical composition from those the model trained on. And in the third one, the model is tested on new aptamer families – sequences that weren’t among the close variants in the training data. This approach makes it possible to test whether a model can work with truly new objects, not just those similar to the one it already knows.
The results demonstrated a significant difference. During standard testing, the ROC-AUC metric (the model’s ability to distinguish binding and non-binding pairs) was 0.95. When working with molecules of previously unknown chemical composition, it went down to 0.89, and with new aptamer families – to 0.87. A different metric is used to predict binding power, R², which shows how close the model’s predictions are to experimental values. In this case, the metric went down from 0.67 to 0.30.
These results demonstrate that if a model performs well in the standard test, this doesn’t guarantee that it can be trusted with searching for new aptamers. AptaBench offers researchers a way to test this before putting the model into practice. Apart from collecting data, the tool’s developers published the code for its processing, as well as basic models that can be used to compare results.
In the future, the researchers are planning to use AptaBench to develop algorithms that will create new aptamers fit to given molecules. In this approach, AptaBench will help verify the reliability of models that evaluate the generated sequences before the most promising of them are sent to be experimentally tested.
The study was conducted within the federal academic leadership program Priority 2030.